
Decide what the summary has to carry
A summary that satisfies nobody in particular drifts towards the opening pages. Name the reader and the decision first, then write the list of things the summary is not allowed to lose, and only then start reading. The list is short: usually five to twelve items, all of them numbers, names or conditions rather than themes.
The document used throughout this guide is the Claude file-upload help article (Upload files to Claude, accessed 2026-09-14). Its must-not-lose list, taken from its own limits section, is: 500MB per file in a chat; up to 20 files per chat; image dimensions up to 8000×8000 pixels; PDFs limited to 1000 pages; project files capped at 30MB each; and a project's file count unlimited only so long as the total fits the context window. Each of those is a figure with a unit and a place in the document. A summary that reports "large files are supported" has carried none of them.
The reader matters as much as the list. Someone deciding whether a 400-page report can be checked needs the page cap and the visual-processing boundary; someone deciding where to paste a contract needs the file size. One summary rarely serves both, and a summary written for neither serves nobody.
Split by the document's own boundaries
Cut at the headings and subheadings the author already wrote. Those headings are the author's statement about where one subject ends and the next begins, and they are the only boundaries a later reader can find again. Splitting at a fixed number of words or characters cuts through the middle of a table caption, separates a condition from the sentence it qualifies, and leaves you with chunks nobody can map back to a page.
Label every note before you use it. Give each one a short identifier — N01, N02, and so on — and mark whether it is a fact the document states, an opinion the document expresses, or a question the document leaves open. Three labels are enough, and they cost a few seconds per note the first time. The payoff is that a proposed heading later has to point at the identifiers that support it, and a heading with no identifiers behind it becomes visible instead of persuasive.
Keep a heading with its body and a table with its caption and footnotes. Record the page range or the heading path for each chunk as you cut it, because the mapping is much harder to rebuild after the fact. In the help article used here, five headed sections carry the whole document, and one of them ("File limits") carries four separate numbers that must travel together.
Carry a small fact register through every pass
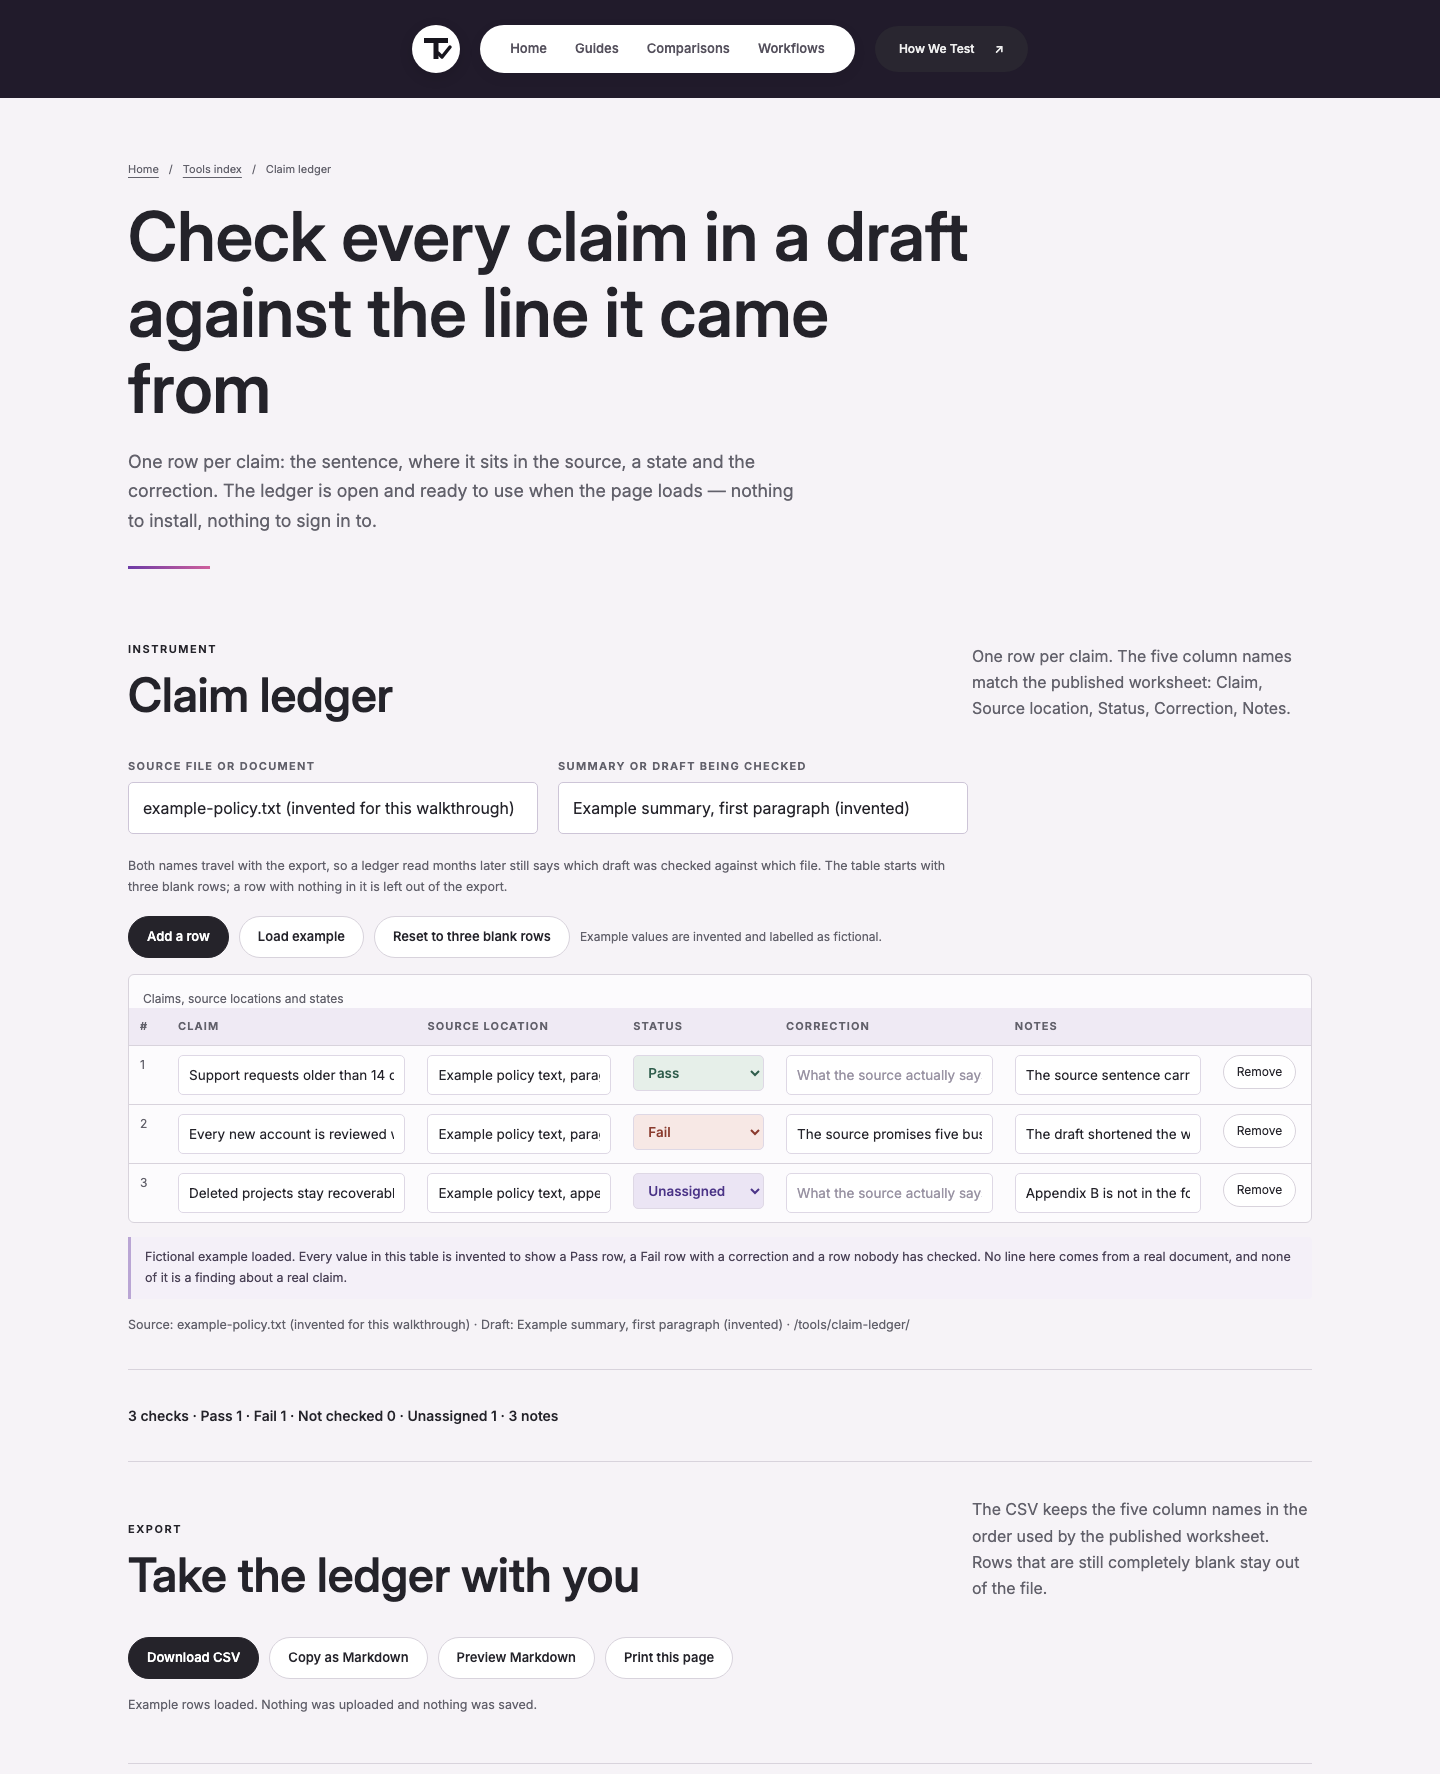
Between one section and the next, hold four fields and nothing more: the claim, where it sits in the source, its status, and a note. Add a correction field for the value the source actually states when the two differ. That is the same five-column shape the published worksheet uses — Claim, Source location, Status, Correction, Notes — and the same one the claim ledger on this site writes into its CSV export.
Update the register at the end of each section, not at the end of the document. Reconstruction at the end is where numbers lose their units and conditions lose their clauses, because by then you are working from your own memory of the text rather than from the text. A register row that reads "30MB" without "per project file" is the beginning of a wrong summary.
Status uses four words and no others. Pass means the source line was found and the claim matches it. Fail means the line was found and the claim does not match. Not checked means nobody has compared the row with the source yet, and it is where every row starts. Unassigned is not a verdict; it marks a row nobody has taken on, so a section you have not reached can sit at Not checked while the row itself is Unassigned. Nothing in the register is scored, counted as a percentage or rated.
One section at a time: add each claim to the claim ledger as you finish a section, then compare the finished summary with the original headings.
Merge sections without flattening disagreement
Two sections of the same document often appear to contradict each other, and the fix is almost never an average. The help article says a project's file count is "Unlimited, but total content must fit within Claude's context window" (accessed 2026-09-14; original wording: "Unlimited, but total content must fit within Claude's context window"). Read carelessly, that says two things at once. Read properly, the count is unlimited and the volume is not, and both halves have to survive into the summary because each one answers a different question a reader will ask.
When the two statements genuinely differ — a total that appears in an introduction and a smaller adjusted figure later in the document — keep both with their context and write down why they might differ. Different populations, different dates and different definitions of the same word explain most of these pairs. If you cannot explain the difference, the summary says so; it does not pick the friendlier number.
Do not let the merge pass invent connective reasoning. Section-by-section work is often blamed for producing disjointed summaries, and the usual repair is to add sentences explaining how the sections relate. Where the document does not state a relationship, the summary should not either.
Worked example: a real document summarized in three passes
The document is the Claude file-upload help article, fetched and worked through on 14 September 2026. After extraction it ran to 47 lines, 383 words and 2,277 bytes across five headed sections. It is deliberately smaller than the kind of document this method is for: at that size every boundary is visible, and the point of the example is to show the three passes rather than to impress with volume. The reader I wrote for is a person deciding whether a long PDF can be handled at all, so the must-not-lose list above is the target.
| Pass | What went in | What came out | What it caught |
|---|---|---|---|
| 1 · Section by section | The five headed sections, each read with its own body text and nothing else | Eleven register rows, each with a claim, a heading as its source location, and a status | Two numbers that look like one: the 1000-page upload cap and the 100-page boundary above which only text is processed |
| 2 · Merge | The eleven rows plus the original heading list | A nine-sentence synthesis in the document's own order | A claim that had quietly moved from the "File limits" heading to "PDF processing", losing the fact that it belongs to PDFs only |
| 3 · Audit | The synthesis against the heading list and the register | The same synthesis with two sentences rewritten and one deleted | An empty section: the synthesis had a "Project files" paragraph with a row that spoke about chatbot uploads |
The first pass produced these register rows, in the order the document presents them. Status is the state of the row after the second pass; nothing is scored.
| Claim | Source location | Status | Correction | Notes |
|---|---|---|---|---|
| Chat uploads accept 500MB per file | File limits, chat uploads | Pass | Unit is per file, not per chat | |
| Up to 20 files per chat | File limits, chat uploads | Pass | ||
| Image dimensions up to 8000×8000 pixels | File limits, chat uploads | Pass | Applies to images, not documents | |
| PDFs are limited to 1000 pages | File limits, chat uploads | Pass | Confirmed again under PDF processing with an error message | |
| Project files are capped at 30MB each | File limits, project files | Pass | Different cap from chat uploads | |
| A project's file count is unlimited | File limits, project files | Fail | Unlimited in count, but the total content must fit the context window | The half-sentence that limits it must travel with it |
| Visual elements are analysed in PDFs | PDF processing | Fail | Analysed in PDFs of 100 pages or fewer; from 101 to 1000 pages, text only | This is the pair the first pass caught |
| PDFs over 1000 pages can be uploaded | PDF processing | Fail | The page states you cannot upload PDFs over 1000 pages | Wording in the source is a refusal, not a limit |
| Non-PDF documents are read as text only | Tips for best results | Pass | Embedded images in them are not read | |
| Images should be at least 1000×1000 pixels | Tips for best results | Pass | Framed as a recommendation, not a requirement | |
| XLSX upload needs a setting enabled | Supported file types | Pass | Conditional on code execution and file creation being on |
Three rows came back Fail, and none of them was a copying error. Each one had dropped the clause that constrained it: a count without its volume limit, a capability without its page boundary, a refusal turned into a permission. That is what a section-by-section pass is for — the same claims survive a single-pass read, because nothing in the sentence itself looks wrong.
Audit the structure before you edit the prose
Before touching a sentence of the synthesis, walk its headings and ask one question of each: does at least one register row support this heading? A heading with eleven rows behind it is safe. A heading with none is a heading you wrote because the outline felt incomplete, and it has to be deleted or marked as a gap rather than filled by inference.
Where a section of the document produced no rows, leave the section visible and empty. An empty section with a note saying nothing was found is a fact about the document. Removing the section hides the gap; filling it with a plausible paragraph invents content; and both make the summary look more complete than the reading was.
Then check the order. A summary's sequence should answer the reader's question, which is not always the order the document collected its material. Reordering is safe; reordering while the register still points at the old heading list is not, so update the locations as you move sections, not afterwards. Two headings that would repeat the same paragraph are one heading.
Keep the register with the summary
The register is the part a reviewer can re-run. Export it at the end of every section rather than once at the end of the job, because a browser tab that closes mid-document takes the unexported rows with it. The claim ledger keeps nothing between visits — it states plainly that "Nothing is stored. No cookie, no browser storage and no account are used, so closing or reloading the tab discards the table" (Claim and source ledger, accessed 2026-09-14; original wording: "Nothing is stored."). Exporting per section is not caution, it is the only copy.
Name the export so it matches the summary, and keep the source's own name beside it. A file called "summary-final-v3.csv" is unreadable six weeks later; "uploads-article_register_2026-09-14.csv" tells the next reader which document the rows came from without opening them.
One thing the register cannot do is judge a paraphrase. It stores the words you typed next to the claim, and a correction that keeps the original syntax while quietly widening what the sentence commits the author to still exports as it was written. The heading-level audit is the only pass that catches that kind of drift, which is why it comes before the prose is edited.
Use the claim ledger for the fact register, one row per claim. Export at the end of each section so a lost pass does not mean lost work.
When the document does not fit one pass
The numbers that decide this are on the provider's pages, not in your intuition. Claude's chat uploads allow 500MB per file and up to 20 files per chat, with PDFs limited to 1000 pages (Upload files to Claude, accessed 2026-09-14; original wording: "Number of pages: PDFs are limited to 1000 pages"). Above 100 pages a PDF is processed as text only, so a chart-heavy deck past that boundary should be split before it is summarised (same page, accessed 2026-09-14; original wording: "For PDFs from 101 to 1000 pages, Claude processes text only and doesn't analyze visual elements").
The context window is the other wall. The current model page lists 1M tokens for Claude Fable 5.1, Claude Opus 5 and Claude Sonnet 5, and 200K tokens for Claude Haiku 4.5 (Models overview, accessed 2026-09-14; original wording: "Context window 1M tokens" for the first three and "200K tokens" for Haiku 4.5). Max output runs to 128K tokens on the three larger models and 64K on Haiku 4.5 (same page, accessed 2026-09-14; original wording: "Max output 128K tokens"). The same page carries the per-token prices, since the size of the job decides the cost: from $1 per million input tokens for Haiku 4.5 to $10 for Fable 5.1, with output from $5 to $50 per million (same page, accessed 2026-09-14; original wording: "$1 / input MTok $5 / output MTok" against "$10 / input MTok $50 / output MTok").
When a document is past any of those walls, split it at headings before uploading rather than asking for a longer context. Keep the chunk map with the register so the next person can see which parts were read and which were not. For decisions with consequences, the summary points at the source; it does not replace it.
Sources behind the numbers on this page
Every limit and price below was read on the page named beside it on 14 September 2026 and is quoted from there. No model was run for this guide and no output length, speed or quality figure is claimed; the document summarised in the worked example was read and counted by hand.
- Upload files to Claude — file types, size and page limits (new tab) (accessed 2026-09-14; original wording: "File size: 500MB per file" · "Number of pages: PDFs are limited to 1000 pages" · "For PDFs from 101 to 1000 pages, Claude processes text only")
- Models overview — context window, max output and per-token pricing (new tab) (accessed 2026-09-14; original wording: "Context window 1M tokens" · "Max output 128K tokens" · "$1 / input MTok $5 / output MTok")
Not checked: the ChatGPT file-upload help article at help.openai.com returned HTTP 403 when requested on 2026-09-14, so no ChatGPT upload limit appears on this page.